Management by Exception · Operating Model
Management by Exception in Oil & Gas Operations.Alarm only on what matters. Rank by what pays.
Management by exception is the operating model behind every efficient upstream operation: limited human attention goes only where the data says it pays, and asset performance improves on the wells you already own.
Definition
What is management by exception in oil and gas?
Management by exception (MBE) is an operating model where leaders and field crews focus attention only on items that have deviated meaningfully from expected performance. Routine, in-spec activity is trusted to continue on its own.
The limited human attention available goes to the small set that has moved out of bounds. Operators reach for it when the goal is to improve asset performance on existing wells: less downtime, less deferred production, lower unit operating cost.
Read more
The discipline traces from Taylor and Drucker through manufacturing and IT ops into oilfield SCADA. Its upstream form, pump by exception, is where most operators start, and it earned real gains wherever alarm discipline held.
After a decade-plus of hard-won industry lessons, WorkSync productized the next step as pump by priority. Whether you are a large operator stalled mid-rollout with the field pushing back, or a smaller operator with no clear place to start, the model is now something you implement in weeks, not years.
In plain terms
Management by exception, in two sentences
Management by exception in oil and gas is a management model in which routine, in-specification activity continues without review, and human attention is spent only on the items that have moved outside an expected range.
It works by defining the expected range for each measurement, detecting deviations from it automatically, and escalating only those deviations to a person who can act on them.
Its upstream application is well surveillance and field routing, where the number of wells is far larger than the number of people available to look at them.
The inversion matters. Manage-by-walk-around scales linearly with headcount: if you double your wells you double your pumpers.
Management by exception scales with software: an exception-based system that continuously monitors 5,000 wells is the same shape as one that monitors 500, only the input data set grows.
In upstream oil and gas this manifests as two specific applications: pump by exception (alarm and visit only deviating wells) and pump by priority (rank the deviations by economic impact, sequence them into a constraint-aware route, learn from every outcome).
Together they replace fixed Monday-Wednesday-Friday route loops with a daily plan that only visits wells where attention is worth the windshield time.
The failure modes
Where exception-based management goes wrong, and how WorkSync fixes it.
| The failure | The WorkSync fix |
|---|---|
Alarm fatigue The failure:Most SCADA-driven exception systems generate hundreds of alarms a shift. | The WorkSync fix:The morning ranked plan is sorted by $, not by timestamp. |
Stale "normal" The failure:Wells decline. Equipment ages. Operating bands shift. | The WorkSync fix:Continuously updated Arps decline forecasts per well, confidence bands per signal, and ML anomaly detection that learns each asset's normal individually rather than against a fleet-wide rule. |
Missing economic ranking The failure:Exception management without economic ranking is just an alarm list. | The WorkSync fix:The stops worth making surface as the daily ranked plan, per crew. |
No closed-loop learning The failure:Exception lists that don't learn from outcomes get progressively worse. | The WorkSync fix:Each week the plan ranks the right work more accurately. |
Read more
Failure mode 01
Alarm fatigue
The failure
Most SCADA-driven exception systems generate hundreds of alarms a shift. Without ranking, crews triage by recency or loudness; the highest-value alarm gets buried.
The WorkSync fix
Continuous economic scoring: every flagged exception carries a dollar-impact estimate and a tier (P1 / P2 / HIGH / MED). The morning ranked plan is sorted by $, not by timestamp.
Failure mode 02
Stale "normal"
The failure
Wells decline. Equipment ages. Operating bands shift. Fixed alarm thresholds, set during commissioning and never updated, produce false negatives (real issues hidden behind a threshold that has crept out from under the well's actual performance) and false positives (alarms that mean nothing).
The WorkSync fix
Continuously updated Arps decline forecasts per well, confidence bands per signal, and ML anomaly detection that learns each asset's normal individually rather than against a fleet-wide rule.
Failure mode 03
Missing economic ranking
The failure
Exception management without economic ranking is just an alarm list. Two wells deviating at the same time may have $12,500/day vs $90/day of revenue at risk (illustrative pair). The spread is invisible without scoring.
The WorkSync fix
Cash-flow-weighted task ranking. Every potential field task scored by dollar-impact. The stops worth making surface as the daily ranked plan, per crew.
Failure mode 04
No closed-loop learning
The failure
Exception lists that don't learn from outcomes get progressively worse. When a flagged exception doesn't pan out, the next similar pattern keeps getting flagged at the same priority.
The WorkSync fix
Reinforcement learning closes the loop. Every completed task feeds outcomes back into the scoring models. Each week the plan ranks the right work more accurately.
WorkSync Research · Volume IV · June 2026
The playbook for fixing all four failure modes, in 15 pages
Taking Pump by Exception to the Next Level is the operator-level implementation guide: prioritized exceptions, economic scoring of alarms, the ranked daily plan, the KPI swap, and a 90-day path gated on evidence rather than the calendar.
The evolution
MBE to pump by exception to pump by priority.
The management philosophy
Human attention goes only to meaningful deviations; routine, in-spec activity runs on its own. Older than the oilfield: Taylor wrote it down in 1903, and every efficient operation practices some version of it.
The oilfield implementation
SCADA brings the philosophy to the wellhead: alarm and visit only deviating wells. Real progress past fixed routes, and the place most operators start.
Its limit is that it stops at detection: the exception arrives with no dollar figure, no route, and no memory. The in-depth guide walks the three layers and the ceiling.
The next step: priced and routed
Keeps the exception discipline and adds what detection lacked: economic scoring on every deviation, constraint-aware routing into a drivable day, and closed-loop learning from every outcome.
The full side-by-side is on Pump by Exception vs Pump by Priority.
The lineage
From Taylor to the oilfield.
1903 · Taylor
1954 · Drucker
1970s · TPS + SPC
1990s · IT Ops
2000s · Pump by Exception
2020s · Pump by Priority
Now · Closed-Loop
Where WorkSync fits
The end-to-end management by exception platform with full closed-loop connectivity between your core corporate functions and your field expertise.
In practice, that closed loop shows up as four outcomes on the same crew
Tackle high-value deferred production
The wells with the most production down and the fastest payback surface at the top of the plan, not wherever the route loop happens to reach them.
Escalate issues efficiently
Exceptions route to the right person with dollar context attached, instead of dying in a group text or a Monday morning meeting.
Manage liquid inventory
Tank levels and haul timing are worked into the same ranked plan, so loads move before tanks top out and wells shut in.
Know when a well stops paying its way
The economic-limit call, made on data: stop putting money into a well that will not pay it back, and redeploy the crew where it will.
Read more
Everyone closes part of the loop. Corporate-workflow agents stop at the office. Lift optimizers stop at the pump.
WellOPS is the world’s most advanced Pump by Exception platform, because it goes beyond flagging exceptions to pricing and routing them. Pump by priority is the next step from pump by exception, and the two are widely treated as the same thing.
If you arrived here on the oilfield term rather than the management one, the software decision itself is laid out on the pump by exception software page.
WorkSync closes the whole loop: corporate systems to the pumper’s ranked plan and back, every shift.
Continue the cluster
Exception management is one piece of the upstream optimization discipline.
The management by exception guides
Go deeper
- How to Implement Management by Exception in Oil and GasThe four hard requirements and the path that works
- Pump by Exception vs Pump by PriorityOne lineage, three generations, defined
- Start Without a Data TeamOne module, one field, no data lake required
- Why Tank Gauging Is DangerousThe safety case for removing the routine visit
The cluster
Companion pillars
- Upstream OptimizationThe umbrella discipline
- What Is Pump by Exception?The in-depth guide: three layers, five failure modes, four rungs
- Pump by Exception SoftwareWhat the software does with the queue you already have
- Pump by PriorityTasks ranked by $ impact
- Four Eras of Field OpsWhere exception fits in the bigger arc
- 90-day Path Era 2 to 4How to upgrade your operating model
- LOE Reduction pillarWhere exception management pays the bill
Capability deep-dives
How the loop closes
Where to start
Modules that run it
- The Productized RolloutThe stand-up playbook: sprints, gates, crews live in weeks
- Work EngineThe ranked plan in every truck cab
- Route Optimizer35% fewer miles driven, deployment figure
- Oilfield Route PlanningThe category guide: routing, dispatch, and how to evaluate it
- Offline Field Data CaptureMobile, voice-enabled, built for the cab
- Field Work ManagementPermits, MOC, lone worker
- DataHubIntegration backbone, included in your WellOPS or FlowSync subscription
- Field Ops Blind Spot Test (no cost)Six questions, find your operating blind spots
More detail
Pump by Exception SoftwarePump by Exception finds problems.
Pump by Priority prices them.
WorkSync prices every exception in dollars per day, ranks the whole field against one ruler, and sequences the ranked list into a drivable day. The plan is in the cab by 6 AM with the work order, the field ticket, and the accrual attached to it.
New to the model, or mapping where you stand today? Read the in-depth guide: the three layers pump by exception runs on, the five ways it stalls at scale, and the four rungs between a threshold queue and a ranked day.
WorkSync prices the exception before anyone decides whether to drive to it.
“…starting to see the benefits of that in terms of moving to a pump-by-exception company, a lot more automation.”
COO, large Permian operator · Q2 2026 earnings call
Pump by Priority is pump by exception, priced. The prioritization engine takes OT data, financial data, and the work record and stitches them into one number per job: dollars per day. Deviation comes from SCADA tags, allocated volumes, and well tests. Value comes from your price deck, your interest, and the production the deviation is actually deferring. Cost and exposure come from equipment history, failure codes, permits, and crew qualifications. One number, one ruler, every open job in the field on it.
That number is the thing a threshold screen has never carried. A 5 BOPD well trips the same color and the same row height as your highest cash flow producer, and on a normal morning the spread between a $200 nuisance signal and a $15,000 production loss runs to more than two orders of magnitude with nothing on the screen to separate them. (The dollar pair is illustrative mechanism, not a measured claim.) Pricing the queue settles the argument with arithmetic.
The ranking then becomes a plan. WorkSync sequences the ranked list into each person’s drivable day, delivers it to the cab by 6 AM, and carries the CMMS work order, the field ticket, and the accrual in the same motion, so the close-out is one screen at the wellhead rather than paperwork at shift end.
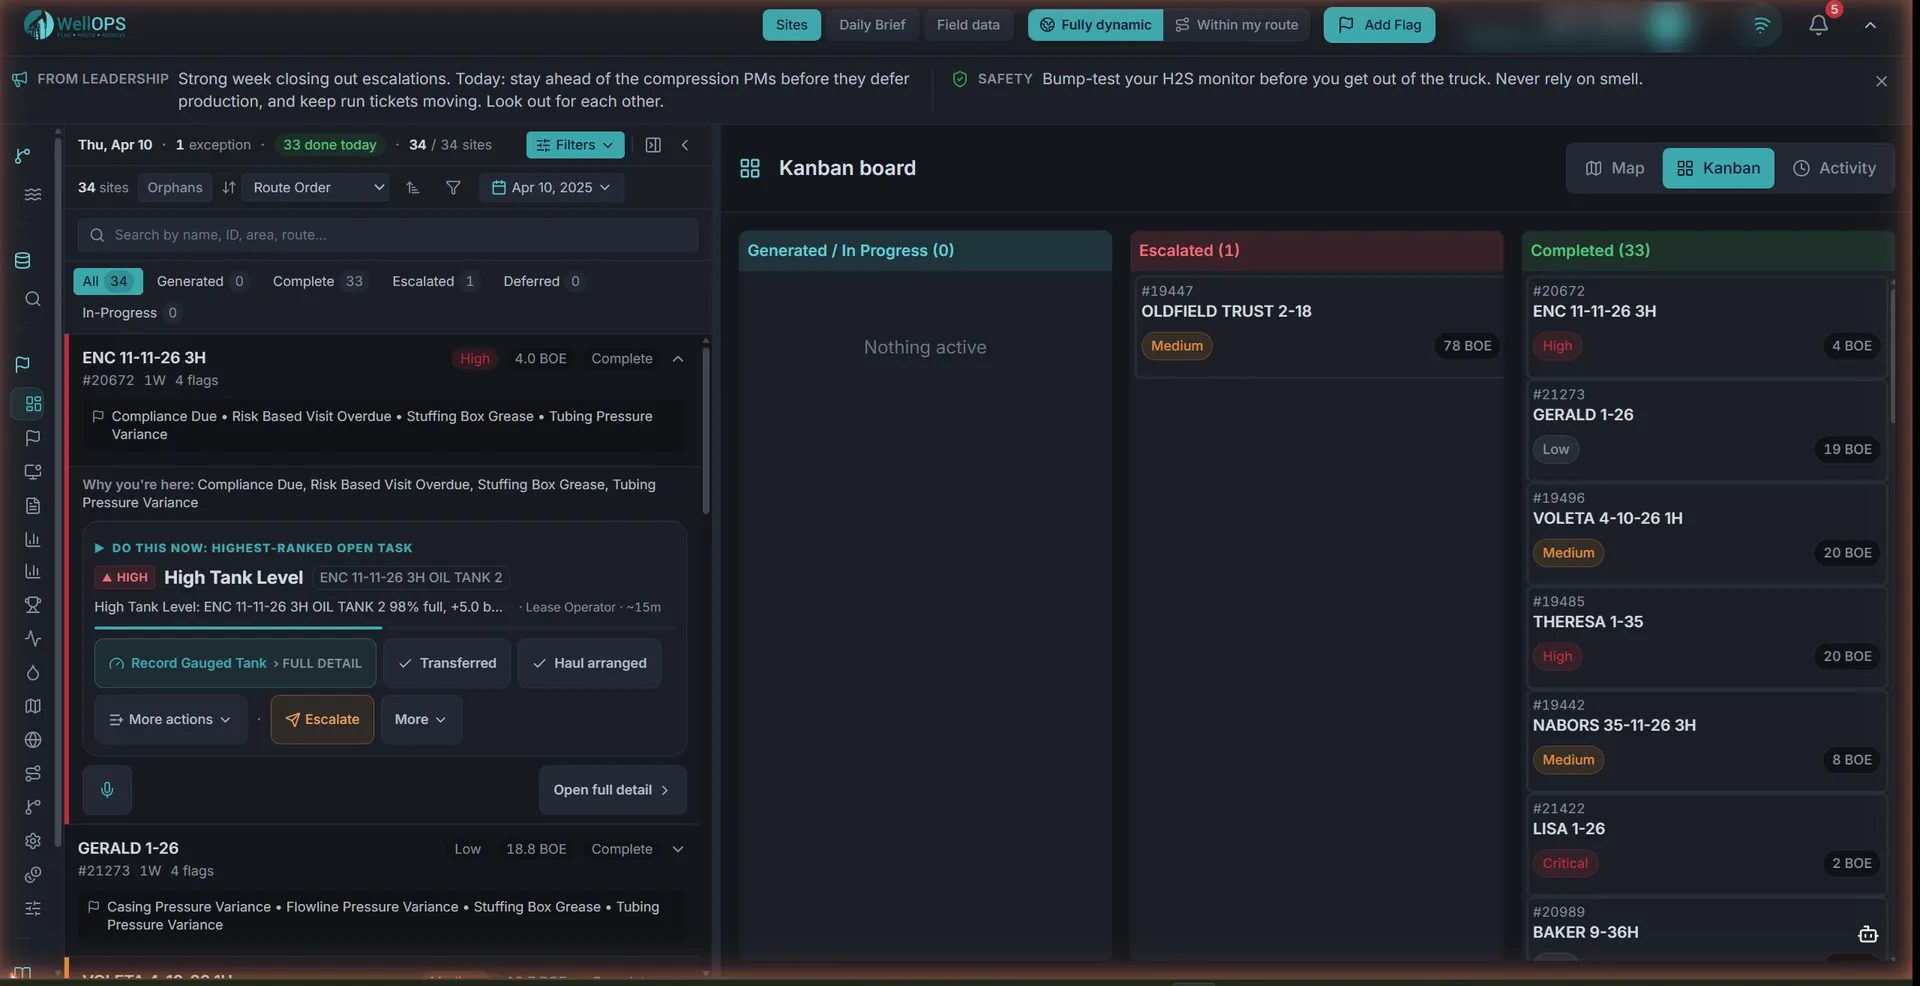
- P1 Battery 14: ESP anomaly, off band 3 days $8.4k/d
- P1 Well 233H: no flow since 04:10, gas-lift restart $5.1k/d
- P2 Well 118: rod pump trending off its own band $2.2k/d
- P3 Well 46: low-rate alarm, deferred with reason $0.2k/d
Fifty exceptions become one ranked plan: every job priced in $/day and ordered by dollars and risk. Illustrative data.
Dispute it. Defer it. Nothing is ever silently suppressed.
A field team member can dispute a flag, which lifts it to the engineer and holds it until resolved. A well already scheduled for workover can be deferred with a reason and stops generating noise. When the control room sees something the system missed, they add the flag and the system reconciles. A list people stop checking is how real problems get masked, so nothing disappears.
Ranking is also overridable, one tap with a reason code, and the override is recorded as data: a well the field consistently pulls forward is carrying information the scoring has not captured yet. Read the six mechanics that keep a ranked plan trusted before you hand one to a crew.
Four kinds of data, stitched into one score.
What goes in
A ranking is only as good as what feeds it. The engine reads four streams on a schedule, over read-only connections to the systems you already run, and resolves them to a single dollars-per-day figure per job.
OT and surveillance
SCADA tags, historian trends, controller states, allocated volumes, and well tests. Deviation is measured against what the well should be doing this week, so a declining well is judged against its own expected curve rather than a limit set the year it was drilled. Thresholds stay current without anyone re-tuning them by hand.
Financial
Your price deck, working and net revenue interest, lifting cost, and the volume the deviation is deferring. A barrel deferred on an oil-weighted well and a barrel deferred on a gassy one price differently, so they rank differently. An hour down is not the same hour everywhere.
Equipment and work history
Failure codes, run life, parts consumed, and the close-out from the last time this equipment failed this way. A well that has failed the same way three times carries that history into its score, and the repeat offenders in the fleet become visible without a data project.
Constraints and data quality
Permits, qualifications, lone-worker rules, and a validation layer that runs first: calibration drift, stuck values, communication gaps, and physically impossible spikes are caught and tagged before they reach the queue. A transducer reading high stops earning a truck roll.
Scoring an unrationalized queue produces precise rankings of garbage, which is why the validation layer runs ahead of the scoring layer rather than beside it. See how deviation is scored and ranked.
Flag, price, rank, route, close, learn.
The closed loop
Closed loop means the last step changes the first one. Six steps run every day, on every well, and the sixth is the one that compounds.
Flag
Every well, every hour. Deviation, liquids, equipment condition, and safety and regulatory exposure all raise flags into one queue. A control room analyst who spots something the models missed adds a flag by hand and it carries the same fields as a machine-raised one.
Price
Each flag resolves to dollars per day: production deferred while it waits, the failure cost if it is left to run, and the exposure it carries. The reason for the number travels with the flag, so the score can be checked rather than believed.
Rank
One ordered list across the whole field, not one list per area or per system. Regulatory deadlines stay absolute where the regulator sets them. Everywhere else, value orders the list and constraints bind it.
Route
The ranked list becomes one drivable day per person, solved against real drive times, crew qualifications, equipment, and hours of service. The plan is in the cab by 6 AM, and it re-solves when a well goes down mid-morning.
Close
One screen at the wellhead, gloves on, online or offline. Readings, volumes, downtime, parts, labor, and the work actually performed are captured once, and the field ticket, the work order, and the accrual are booked with the work, not at month-end.
Learn
The close-out answers the question the queue was asking: was this exception worth the visit? Recovered production is measured against the estimate, disputes and overrides are recorded with their reason codes, and both feed the scoring that runs the following week. A well the field keeps pulling forward is carrying information the model has not captured yet.
Two operators can buy identical software. The one whose operating model feeds outcomes back accumulates calibration the other never gets, and the gap widens every quarter. Read the guide on what keeps a ranked plan trusted.
What operators get. In this order.
Downtime Reduction
WorkSync works the exception that is costing money first. Every flag arrives carrying what the deviation is worth per day, not just the fact that a threshold tripped.
Optimal Liquid Management
Tank state, fluid levels, and hauling raise exceptions on the same ruler as the wells, so a tank heading for a shut-in outranks a nuisance alarm.
Proactive Risk Management
The engine attaches permit, qualification, and integrity constraints to the exception itself, so the riskiest flag is scheduled with what it needs to be worked safely.
The Full Picture of Value Sinks
Every flag, deferral, and close-out lands in one ledger. The exceptions nobody worked are visible before the variance review finds them.
Every site raises its hand. Only some of them are worth the drive.
How an exception becomes a ranked job
The engine that turns a threshold breach into a priced, sequenced, crew-matched job: what goes into the score, how constraints bind it, and how the close-out feeds back.
Already running pump by exception and weighing the move?
The long answers, the three-layer mechanism, and the maturity ladder are in the in-depth guide.
The side-by-side comparison and the migration path are at pump by exception vs pump by priority.
Exception-Based Surveillance (EBS) in Oil and GasException-Based Surveillance.
Run the score, not the calendar.
Exception-based surveillance (EBS) is the upstream operating framework that ranks every field action by a quantitative score derived from the data already in the historian, the SCADA, the accounting system, and the EAM. The crew does not visit wells on a calendar rotation. The crew visits wells whose signal moved. It is the research-grade ancestor of pump by priority, and the framework behind the productivity numbers the industry has been quoting for a decade.
Exception-based surveillance, in two sentences
Exception-based surveillance in oil and gas is a monitoring approach in which engineers and field crews review only the wells whose measured behavior has deviated from an expected range, instead of reviewing every well on a fixed schedule. It works by comparing each well’s live measurements against a modeled or statistical expectation, raising an exception when the gap passes a threshold, and sending that exception to a person with the supporting trend attached. Wells inside their expected range generate no work, which is what lets the approach scale to a large well count without scaling the headcount.
The framework was defined by independent research, not by a vendor.
The independent receipt
Alvarez & Marsal published the canonical definition in 2015 in “The Advantages of Exception-Based Surveillance,” a whitepaper that put defensible numbers on what operations leaders at the largest operators had been doing informally for years. The study is the independent receipt for the whole exception-management category: it predates the current software generation, it was not written to sell a platform, and its two anchor findings have held up across a decade of subsequent deployments.
25% → 60% Lease operator value-added time, fixed routes vs exception-driven operations. (Alvarez & Marsal, 2015)
One operator has published the same pattern at scale: a closed-loop gas-lift optimization workflow deployed by ExxonMobil across more than 1,300 Permian wells reported about 2% average oil uplift, with no surface or downhole equipment changes (SPE-219553, SPE Artificial Lift Conference and Exhibition, 2024; conference paper, not peer reviewed; summarized in JPT, October 2024).
Where the fixed-route model leaks value.
The default it replaces
Walk into any 500-well operation still running fixed routes and three patterns show up in under an hour.
- The highest-value well does not get the most attention: a high-rate well drifting off forecast and a low-rate well running steady get the same number of visits per week, even though the dollars at risk differ by an order of magnitude.
- Equipment failure gets discovered late: the degradation signal was in the historian days before the pumper opened the lease gate, but nobody scored it, so the well is down for hours before anyone knows and down for days before the workover finishes.
- The route stays busy while the number stays flat: plenty of miles, plenty of tickets, and an aggregate effect on production that rounds to zero, because none of the work was the work that mattered.
EBS does not add work to the pumper’s day. It changes the order. The route opens on the highest-scored well in the basin rather than the next stop on the calendar; wells whose signal did not move fall off; wells whose signal did move land at the top. Same crew, more high-value visits per shift, because the low-value visits are not there. Run for long enough, the standing route stops being the unit of planning at all: what routeless operations look like day to day.
Most operators know this framework by the name the oilfield gave it. The implementation, the three layers it runs on, and the five ways it stalls once the queue outgrows the attention available to read it are worked through in the guide to how pump by exception works in practice.
The three operating levers.
Inside the framework
The research, the case studies, and the production deployments all decompose EBS the same way. Each lever moves a different line on the operating budget.
Preventative maintenance
Catch equipment degradation early enough to intervene at scheduled cost rather than emergency cost. The signal is already in the historian; the score ranks every lift unit and facility by probability of an intervention-worthy event and the cash flow at risk on the asset. The workover crew schedules against the forecast, not against the failure.
Dispatch and rerouting
Reorder the route every morning against the overnight score. The pumper, the foreman, the well tester, and the workover rig all see the same ranked plan by 6 AM. Calendar visits drop, exception visits rise, and the value-added share of the crew day climbs.
Closed-loop lift and production control
Run setpoint recommendations on artificial lift, separator pressures, and choke schedules against the live score. The controller accepts or rejects; the model retrains overnight. Most operators add this lever after the first two have made the data hygiene durable.
Surveillance, at the site level.
On a Tuesday morning
Every site carries its own read: open work, actions in progress, required JSAs, value at risk by tier, and the visit pacing behind it. When the score says a routine visit is all a site needs, the crew knows that too, and the freed time goes to the well whose signal moved.
EBS is the framework. Pump by priority is its modern scoring layer.
Classical EBS, as defined in 2015, ranks exceptions by severity. Pump by priority adds explicit cash-flow weighting, constraint-aware routing, and closed-loop learning, so a separator nuisance alarm and a high-value well drifting off forecast stop arriving with equal urgency. WorkSync ships that layer as a product: WellOPS deploys read-only onto the SCADA, historian, production accounting, EAM, and GIS stack you already run, and puts the ranked plan in the truck cab by 6 AM. If your team is already running an exception queue and the question is what to buy on top of it, that decision is laid out on what to buy on top of an exception queue.
The adoption path mirrors the research: no sensor refresh, no data-lake project, no multi-year integration. Week 0, sign one metric. Week 1, read-only integration. Weeks 2 and 3, the score runs nightly and the plan hits the truck cab. Week 4, measure and decide. The deployed reference, a top 25 private producer running 5,000+ wells across the Western Anadarko, Permian, and Wyoming, followed this shape and delivered a 15% free cash flow uplift on the same crew and 35% fewer miles driven, measured in live deployments. The full labeled proof set is on the numbers page.
The window for treating this as optional is closing: continuous-monitoring requirements are arriving across onshore tank fleets, the operators with the most basin position have already productionized the framework, and the lease operator with two decades of basin knowledge is retiring. The operating model has to be in place before the institutional knowledge walks out.
Are your best people working on your most valuable work today?
Run the score on your own wells.
Four weeks from read-only integration to a ranked plan in the truck cab, against one signed metric.
Continue the cluster: Pump by Exception vs Pump by Priority · Management by Exception in Oil & Gas Operations · WellOPS, the platform that runs pump by priority
Production Surveillance Software for Oil and GasProduction Surveillance Is End to End or It Is Theater.
WellOPS Production Surveillance
Most operators run production monitoring and call it surveillance. The difference is five elements: detect, score, route, execute, learn. WellOPS runs the full loop on the SCADA, historian, accounting, and EAM stack you already own, and puts a ranked, dollar-denominated plan in every truck cab by 6 AM.
The Word Migrated. The Action Half Fell Off.
Production surveillance is a phrase the industry has used since the late 1980s. It came out of the major-IOC field-of-the-future programs that put control rooms behind every offshore complex. In that context the term meant something specific: a small team of engineers, sitting in a centralized room, watching live signal from a producing asset, and intervening when the signal said to intervene. That room has an onshore descendant, and independents run it today as a remote operations center.
By the mid-2010s a dashboard built on top of a historian was calling itself the same thing. By 2026 the term covers any software that displays a production number on a screen. The action half of the original definition quietly fell off. The watching half got rebranded as “real-time visibility.”
The result is that most independent operators describe themselves as running production surveillance and run nothing of the kind. They run production monitoring. The two words look similar. They do completely different things to free cash flow.
Run end to end, production surveillance is management by exception applied to producing wells: watch every well continuously, act only where the deviation pays. The oilfield’s own name for the first half of that, and the reason it plateaus once the queue grows, is covered in the guide to pump by exception and its ceiling.
The Five Elements of Real Production Surveillance
The complete definition runs end to end. Five elements, each of which has to actually happen. Drop any one and the loop opens. The cash flow leaks out the gap.
1. Detect
Live signal from SCADA, well tests, run tickets, deferment data, inspections, and route history is read continuously. ML models calibrated to each well's normal behavior catch deviations the static-threshold alarm misses. Most operators have this. It is necessary and far from sufficient.
2. Score
Every detected anomaly is scored in dollars, not in alarm severity. Production at risk, working interest, lifting cost, commodity strip, deferment risk. A stuck valve on a 5 BOPD stripper at $60 oil scores below a failing rod pump on a 200 BOPD producer at $80 oil. The output is a ranked list denominated in cash flow.
3. Route
The scored anomaly is sequenced against the crew roster, qualified by skill match and equipment dependency, bounded by hours of service, and assigned. A constraint-aware optimizer turns the ranked list into an executable plan, not a suggestion.
4. Execute
The work lands in the truck cab on a mobile surface the pumper actually uses. The Willie voice agent runs the JSA. The form fills itself from SCADA and the last shift. The operator confirms what is true. Outcome is captured against the originating anomaly.
5. Learn
The outcome feeds back into the detection model and the scoring model overnight. Tomorrow's plan reflects what the field did yesterday. False alarms drop. Ranking accuracy compounds. The system is measurably better next quarter than it is today.
If any one of those five is missing, the result is not production surveillance. It is one of the four partial states most operators are in today: monitoring without ranking, ranking without routing, routing without execution feedback, or execution without learning. Each partial state leaves a measurable fraction of the cash flow in the field.
Where Most Operators Actually Sit on the Loop
The honest assessment that comes out of the 24-hour AI operations diagnostic puts most independents somewhere on the same five-stop maturity ladder. The pattern is consistent enough to be useful.
● Stop 1 only. SCADA alarming on threshold breaches. No central screen, no consolidated plan. Fixed routes regardless of overnight changes.
● Stops 1 to 2. Most independents. SCADA plus a historian-based dashboard plus a 7 AM flash report. Route still gets cut against habit and proximity.
● Stops 1 to 3. Detection and scoring in place. Ranked list lives in a dashboard or daily report. Execution still set by the foreman texting at 5:30 AM.
● Stops 1 to 4. Ranked plan sequenced and delivered in cab. Work gets done. Outcome not captured back into the model, so the system never learns.
● Stops 1 to 5. The supermajors and the top quartile of Lower-48 independents. The full loop runs nightly.
The operating delta between the top quartile and everyone else, measured at the free cash flow line, is the gap now showing up at every RBL redetermination cycle and PE term sheet. The supermajors are naming the loop on earnings calls. The independents who close the gap this year compound. The ones who wait keep paying the deferment tax and keep watching their pilots stall.
Dashboard vs. Pump by Exception vs. WellOPS Production Surveillance
Three things the industry uses the word “surveillance” for, side by side, by what they actually deliver to the day of the shift.
| SCADA Dashboard | Pump by Exception | WellOPS Production Surveillance | |
|---|---|---|---|
| What it does | Displays live production data on a screen | Dispatches a crew when an alarm trips | Runs the full detect, score, route, execute, learn loop |
| Where the loop stops | Detect (element 1) | Detect + partial Execute (elements 1 and 4) | Closed end to end |
| Day-of-shift output | A wall of trends and a list of alarms | A list of alarms, treated as equally urgent | Ranked, dollar-denominated daily plan in every truck cab by 6 AM |
| Field-team behavior change | Foreman reads the dashboard, texts the crew | Crew reacts to alarms in proximity order | Field works the highest-value task first, by default |
| Closed learning | None. Same alarm fires the same way next quarter | None. Static rules, manual tuning | Yes. Nightly model retraining on captured outcomes |
| Free cash flow impact | ~0 measured against monitoring baseline | Fewer unnecessary visits, gains erode with alarm fatigue | 15% FCF uplift on the same well count (5,000+ well reference) |
| Buyer signal | Era 1 to Era 2 on the maturity ladder | Era 2 on the maturity ladder | Era 4 on the maturity ladder |
Why WellOPS Production Surveillance Is the Version You Can Buy This Quarter
WellOPS runs production surveillance end to end. Detection on top of the SCADA, well test, run ticket, and deferment data the operator already runs. Scoring on the operator’s actual economics, not alarm severity. Routing against the crew roster, the skill matrix, the equipment dependencies, and the geography. Execution in the truck cab through the Field Data Capture surface and the Willie voice agent, so the pumper does not type a form at the end of a long shift. Learning that runs nightly so the next morning’s plan reflects what the field did yesterday.
The deployment shape mirrors the four-week pump-by-priority pilot. Week one to integrate read-only through the DataHub over the existing stack. Weeks two and three to put the ranked plan in the cab. Week four to measure against a metric the controller signs for on day zero. The Impact Guarantee carries the financial risk: if the metric does not move past the threshold, the operator walks away with the integration documentation and the baseline dataset. No license fee. No kill fee.
The architecture is the same shape on a 200-well operation as on the 5,000-plus-well, three-basin deployed reference at a top 25 private producer across the Western Anadarko, Permian, and Wyoming. The closed loop scales because it was designed as a closed loop, not as a dashboard that grew downstream attachments.
Keep Reading
Related Resources
Dive deeper into how WorkSync transforms operations.
Increase Production With the Crew You Already Have
The capacity argument: surveillance that ends in a ranked, routed field day instead of a report.
What the A&M 2015 Worked Example Assumes
The hypothetical 10,000 BOPD example behind the exception-based surveillance maintenance lever (modeled, illustrative), and the four-week adoption path.
How overnight detection catches deferred production, the first element of the loop.
Exception-Based Surveillance
The supermajor playbook the independents still do not run, and what it takes to adopt it in four weeks.
The economic-ranking element of the loop, scored in dollars not alarm severity.
Pump by Exception
Where the industry started. Why it stops one element short of a complete loop.
The field operations product that runs Production Surveillance end to end, with Willie riding shotgun.
The 4-Week Pump-by-Priority Pilot
What actually happens, week by week, including the Impact Guarantee clause.
Run the full loop on your data. See it in four weeks.
WellOPS Production Surveillance runs detect, score, route, execute, learn on the systems you already own. Ranked plan in every truck cab by 6 AM. Impact Guarantee in writing.
Frequently asked
What VPs of Ops ask about exception-based management.
What is management by exception in oil and gas?
Management by exception is an operating model where attention goes only to the assets that have moved meaningfully away from expected performance. Routine, in-spec activity is left to run.
In oil and gas it is adopted to improve performance on wells an operator already owns: less deferred production, fewer avoidable failures, lower unit operating cost from the same crew. The idea originates with Frederick W.
Taylor's Shop Management (1903), was carried into the modern management canon by Peter Drucker, and reached upstream through SCADA-driven exception alarms in the 2000s.
How is management by exception different from pump by exception and pump by priority?
They are three rungs of the same ladder. Management by exception is the operating model: act only where the data says action is warranted.
Pump by exception is the industry's first-generation implementation of it: SCADA thresholds flag wells that deviate, and crews visit what is flagged.
Pump by priority is the productized next step: the flagged exceptions are scored in dollars, sequenced into a constraint-aware route for the crews and qualifications actually available, and every field outcome is fed back so next week's ranking is better.
An operator can be doing pump by exception and still not be managing by exception, because an unranked alarm list does not allocate the day.
What do we need in place before we can run it?
Three things, and most operators have only the first. (1) A definition of normal per asset: a continuously updated decline forecast, an expected pressure band, an expected runtime envelope. Fixed thresholds set at commissioning are not a definition of normal, because wells decline underneath them.
(2) A scoring layer that converts each deviation into dollars at risk, so a separator nuisance alarm and a high-rate well drifting off forecast stop arriving with equal urgency.
(3) A delivery layer that puts the ranked result in the field team's hands before the shift starts. WorkSync reads the SCADA or historian, production accounting, EAM or CMMS, and GIS systems already in place, read-only, and the ranked plan is live in 4 weeks.
Does this work if only part of our field has SCADA?
Yes, with a limit worth stating plainly. Exception detection is only as good as the signal, so a well with no telemetry cannot generate a real-time exception.
Those wells are still ranked, using what does exist: production accounting volumes, run tickets, gauge and haul history, work-order and failure history, and the decline forecast.
They stay on a time-based cadence until better signal exists, and they are visibly labelled that way rather than quietly treated as healthy. Partial coverage is the normal starting condition, not a disqualifier, and the ranking improves as instrumentation grows.
What changes for a field team member day to day?
The work does not get heavier, the order changes.
Instead of a standing route driven Monday, Wednesday, and Friday, the crew opens a plan that was rebuilt overnight: the wells whose signal moved are at the top with the dollars at risk attached, the wells whose signal did not move are not on the list.
Escalation carries the same economic context, so an exception routes to the right person with a number beside it.
In the reference deployment at a top 25 private producer, the same crew drove 35% fewer miles (deployment figure) and the operation measured a 15% free cash flow uplift on the same crew (deployment figure).
What are the advantages and disadvantages of management by exception?
The advantage is leverage. Attention is finite and wells are not, so pointing the attention at the small set that has moved buys capacity that headcount would otherwise have to buy.
It also makes the operation legible: what got worked, and why, becomes a record instead of a habit. The limits are real and worth naming before you build on it.
The model is only as good as the definition of normal behind it, so a stale baseline hides problems as effectively as it raises false ones.
It says nothing about magnitude on its own, so a deviation worth $90 a day and a deviation worth $12,500 a day arrive with equal urgency until something prices them (illustrative pair).
It can starve the routine work that keeps deviations rare, which is why preventive and regulatory work has to compete in the same ranking rather than sit outside it.
And it needs signal: an asset with no telemetry generates no exception, so partial coverage has to be visible rather than read as health. Each of those limits is a missing layer above the detection, which is what the ranking, scoring, and feedback layers supply.
How do you measure whether management by exception is working?
Pick the operating metric first and baseline it before anything is connected. Four measures separate a working program from a busy one. Deferred production, because the point of ranking is that the expensive deviations get worked first.
Operating cost per well on the same crew, because the model claims capacity rather than headcount. Miles or hours driven per unit of economic coverage, because a plan that removes low-value stops shows up here before it shows up anywhere else.
And the share of exceptions that turned out to be worth the visit, which is the only measure that tells you whether the queue itself is improving.
At the deployed reference, a top 25 private producer running 5,000+ wells, the measured deployment figures are a 15% free cash flow uplift on the same crew and 35% fewer miles driven for the same coverage.
What usually goes wrong when operators try this?
Four failure modes account for most of it. Alarm fatigue: hundreds of exceptions a shift with no ranking, so crews triage by recency and the highest-value item gets buried.
Stale normal: baselines that do not move as wells decline, producing both false alarms and missed real ones.
Missing economic ranking: exceptions worked in the order they arrived rather than the order they pay, which is the difference between a busy field and a productive one.
No closed-loop learning: when a flagged exception turns out to be nothing, the next identical pattern is flagged at exactly the same priority.
All four are ranking and feedback problems rather than sensor problems, which is why buying more instrumentation rarely fixes them on its own.
What is pump by exception software?
Pump by exception software is the tooling layer that turns SCADA readings into a field work signal: it holds the normal operating window for each parameter, watches live and historian data against it, raises an exception when a reading leaves the window, and delivers that exception to a field team member on a phone or tablet.
The category as it is sold today stops at the alert. What happens next, deciding which of the open exceptions is worth a truck this morning, is still a person with a list.
What should pump by exception software do after it flags the alarm?
Four things, and they are the buying criteria worth writing down. Price it: the flag arrives carrying production at risk per day of inaction at your working interest and your price deck, not just the fact that a threshold tripped.
Rank it: every open job in the field sits on one ruler, so maintenance, safety, regulatory and production work compete on the same number.
Route it: the ranked list is solved into one drivable day per person against real drive times, crew qualifications and hours of service.
Learn from it: the close-out records whether the exception was worth the visit, and that answer feeds the ranking that runs the following week.
Do we have to replace our SCADA or exception system to add pricing and routing?
No. The scoring, routing, and feedback layers read from the SCADA, historian, and alarm discipline you already run, over read-only connections, with nothing placed on your control network. Nothing is migrated and no system of record moves.
The exception engine you bought keeps doing exactly the job it does today, and the layers above it consume what it already produces.
How long does it take to get pump by exception software running?
Four weeks to crews live, on one field, against one metric you pick before anything is connected. Week one is read-only integration to the SCADA or historian, production accounting, and the EAM or CMMS already in place. Week two stands up the scoring.
Weeks three and four put the ranked plan in the truck cab and measure it against your own baseline. The stand-up is a real production deployment on your data rather than a sandbox.
How do we justify this internally?
Build the case from a method rather than a projection. First, you and your controller pick one operating metric and write it down before anything is connected: cash flow per BOE, operating cost per well, drive miles, or TRIR.
Second, run your own well count, crew count, and drive times through the route economics calculator on this site, which puts a dollar figure on a day of your field capacity using your inputs rather than ours.
Third, run the four-week pilot on one field against that single agreed metric, with the baseline set in week zero, so the business case is measured on your wells.
The Impact Guarantee carries the commercial risk while that happens: license fees only when the metrics move. What reaches your approver is your own baseline and your own delta, which is the only version of the number that survives a finance review.
How is pump by exception software priced?
Under the Impact Guarantee: license fees only when the metrics move. You and your controller sign one operating metric at the start, cash flow per BOE, operating cost per well, TRIR, or drive miles, and the 4-week stand-up runs on the stack you already own.
What drives the size of a deployment is the number of fields in scope, how many systems of record have to be connected, the module mix, crew count, and how ready the data is.
Scoping those with the implementation team is the conversation, not a price list.
What is exception-based surveillance in oil and gas?
Exception-based surveillance (EBS) is an upstream operating framework that ranks every field action by a quantitative score derived from continuous monitoring of the data already in the historian, the SCADA, the accounting system, and the EAM.
The crew does not visit wells on a calendar rotation; the crew visits wells whose signal moved. Alvarez & Marsal published the canonical definition in 2015 in "The Advantages of Exception-Based Surveillance."
Who first defined EBS and where are the numbers from?
The canonical definition was published by Alvarez & Marsal in their 2015 whitepaper "The Advantages of Exception-Based Surveillance."
Two figures from that paper are worth knowing, and both are illustrative models rather than measured results: lease operator value-added time rises from approximately 25% under fixed routes to approximately 60% under EBS, and its worked example assumes a one-third reduction in maintenance downtime, 7.5% to 5.0%, on a hypothetical 10,000 BOPD field (modeled, illustrative).
What are the three operating levers inside EBS?
Lever one is preventative maintenance: intervene at scheduled cost instead of emergency cost. Lever two is dispatch and rerouting: rebuild the route every morning from the overnight score. Lever three is closed-loop lift and production control: run setpoint changes against the live score.
The levers do not have to deploy in parallel; most independents start with the first two and add the third once data hygiene is durable.
Does EBS require new sensors or a SCADA refresh?
No. The published EBS results were produced on data the operators already had. The framework deploys read-only onto the existing SCADA, historian, production accounting, EAM, and GIS stack. New sensors earn their place on individual well ROI math after the score is running, not before.
How does EBS differ from alarm management?
Alarm management catches discrete threshold violations.
EBS adds two things: the exception is scored (ranked by cash flow at risk and probability of an intervention-worthy event, so the crew sees the highest-value work first) and the exception is multi-source (the score combines SCADA, historian trends, accounting variances, and work-order history, so slow degradation patterns no single alarm would catch still surface in the morning plan).
What is the relationship between EBS and pump by priority?
EBS is the framework; pump by priority is the modern scoring layer inside it. Classical EBS ranks exceptions by severity. Pump by priority adds explicit cash-flow weighting, constraint-aware routing, and a closed-loop feedback signal so the score gets sharper after every field observation.
EBS says: run the score, not the calendar. Pump by priority says: make the score a dollar figure and make the output a drivable day.
What is the four-week EBS adoption path?
Week 0: the operations leader and controller pick one metric and sign the threshold on one page. Week 1: read-only integration on the existing stack.
Weeks 2 and 3: the scoring loop runs nightly and the ranked plan is in the truck cab by 6 AM. Week 4: measure against the baseline and decide. Under the Impact Guarantee, if the metric did not move, you owe no license fee.
What is production surveillance in oil and gas?
Production surveillance is the end-to-end operating discipline that takes a live signal from each well, detects deviations from learned normal behavior, scores the anomaly by estimated dollar impact, sequences the work into a constraint-aware daily plan, delivers it to the crew in the truck cab, and feeds the captured outcome back into the model overnight.
Five elements: detect, score, route, execute, learn. Any version of surveillance that stops at the dashboard is doing one or two of the five and leaving the rest on the table.
How is production surveillance different from production monitoring?
Production monitoring puts a live or near-live production number in front of a human. SCADA HMIs, morning flash reports, exception dashboards, and historian portals are all monitoring tools. Monitoring is a precondition for surveillance, not a substitute.
Surveillance runs the full loop, and the gap between the two is what the loop is worth: 15% more free cash flow on the same crew, measured across 5,000+ wells in live deployments.
How is production surveillance different from pump by exception?
Pump by exception is the detection element only. An alarm trips when a measurement crosses a static threshold and a crew is dispatched. It treats every alarm as equally urgent and stops at the truck roll.
Production surveillance adds economic scoring, constraint-aware routing, in-cab execution, and a closed learning loop. Exception cases get worked alongside high-value preventive work, not after it.
Do I need new sensors or new SCADA to run production surveillance?
No. The five-element loop runs on the data the operator already has. The detection layer learns each well's normal behavior from the signal already flowing through SCADA, well tests, run tickets, and the historian.
More data sharpens the model; less data still produces a ranked plan. The 24-hour AI operations diagnostic also surfaces where SCADA or instrumentation investment would pay back fastest if it is not yet in place.
What does WellOPS Production Surveillance integrate with?
WellOPS reads through the DataHub integration layer in read-only mode by default, with write-back opt-in per system.
Pre-built connectors cover production accounting (P2, Quorum, Enverus), EAM (Maximo, SAP PM, IFS), SCADA and historian (AVEVA PI System, Cygnet, Ignition, AVEVA), engineering (AVEVA, Siemens, AutoCAD), documents (SharePoint, OpenText), compliance (Intelex, Sphera), and GIS (Esri). Forty-plus connectors, not a forty-week integration program.
How long does WellOPS Production Surveillance take to deploy?
The deployment shape mirrors the four-week pump-by-priority pilot. Week one to integrate read-only across the existing stack. Weeks two and three to put the ranked plan in the truck cab through Field Data Capture and the Willie voice agent.
Week four to measure against a metric the controller signs for on day zero. The Impact Guarantee carries the financial risk: if the metric does not move past the threshold, the operator walks away with the integration documentation and the baseline dataset.
License fees only when the metrics move.
What results should I expect from running production surveillance end to end?
On the deployed three-basin reference at a top 25 private producer (5,000+ wells across the Western Anadarko, Permian, and Wyoming) the loop has produced 15 percent or more free cash flow uplift on the same well count, and 35 percent fewer miles driven with higher task completion at the high-value sites.
Those are deployment figures on one operation, and the 4-week pilot measures the same ones on your own field before anything else is decided.
Is production surveillance only for large operators?
No. The closed-loop architecture scales down further than the supermajor case studies suggest. An operator with 200 wells, a single SCADA system, a production accounting feed, and an EAM tool has enough operating data for the loop to produce ranked field decisions on day one.
The four-week pilot is sized to fit that scale and produces a measurable dataset for the RBL redetermination conversation and the PE term sheet.
See exception-based ranking on your data.
Talk to our team about how management by exception can be run on your wells. The 4-week stand-up is credited toward your first license. Move the metric you anchored on, or you owe no license fee.