Customer outcomes
Same crew. Same wells. 15% more free cash flow.
A top 25 private producer runs 5,000+ wells across three basins. The field day used to be set the way most field days are set: fixed routes, an exception list nobody had time to price, and one experienced person ranking tomorrow by hand.
The crew was fully occupied and the most valuable work still waited. WellOPS prices every exception in dollars per day, ranks the whole day on one economic ruler, and routes the crew to it.
Measured against the pre-deployment baseline on the same asset base and the same headcount: 15% more free cash flow and 35% fewer field miles at the same production coverage.
Against the pre-deployment baseline = 100
Measured, live deployment · same crew
Measured, live deployment · same production coverage
Deployment figures measured across 5,000+ wells in live operations at a top 25 private producer. Results are not projections. What transfers to your operation is exactly what the pilot measures.
The transformation
Five things about the operating pattern changed. Each one is a mechanism.
| Before | After |
|---|---|
Routes by habit Before:The same wells on the same days, because that is how the route was drawn. | After:35% fewer miles driven at the same production coverage.deployment figure, same production coverage |
Alarm overload Before:Every exception arrives the same size. A nuisance trip reads like a failing lift system. | After:The day is ordered by dollars, and recovery work runs biggest dollars first.ranking behavior, not a published statistic |
Manual prioritization Before:One experienced person reads all of it and ranks tomorrow by hand, from memory and judgment, every morning. | After:The ranking covers every well, survives past mid-shift, and stays with the operation when its author retires.ranking behavior, not a published statistic |
Fragmented work Before:Six classes of work share one shift, each planned where it originates, and the couplings between them belong to nobody. | After:60% less redundant tank gauging, 40% lower liquid-hauling inventory, and zero tank-induced shut-ins.deployment figures on the covered tank-battery population |
Delayed accruals Before:What the field found and what it did land in the numbers at month close, weeks after anyone can act on either. | After:Finance sees the work as it happens, and each day ranks on a model the last day taught.system behavior |
The left column is the general operating pattern in production operations, documented in the white papers linked below. The right column is measured.
After column, in order: deployment figure, same production coverage; ranking behavior, not a published statistic; ranking behavior, not a published statistic; deployment figures on the covered tank-battery population; system behavior. The full labeled set, with the method behind each number, is on the numbers page.
Before
The operating pattern, before anything is ranked.
This is the general pattern in production operations, the one the WorkSync white papers document and the one most fields still run today. It is described here as the pattern, not as a portrait of any one customer.
It is worth reading closely, because each item below is what a specific piece of the platform was built to replace.
Routes are drawn once and then repeated
A route built around geography and visit frequency sends a crew past the same wells on the same weekday for years.
It is stable, it is easy to staff, and it spends the same hour on a well making 4 barrels and a well making 400. The economics of the stop never enter the decision, because the decision was made when the route was drawn.
Exceptions arrive faster than anyone can price them
Exception-based monitoring is a real advance, and it hits a ceiling: it tells a control room that something changed, at a rate no control room can triage.
The exceptions arrive with no dollars attached, so the ones that get worked are the loud ones, the familiar ones, and the ones nearest the truck.
Priority is a person, not a system
Somebody senior reads the alarms, the downtime report, the work-order backlog, and the engineering recommendations, and decides the day. That judgment is genuinely good.
It also gets triaged from memory, covers the wells one person can hold in their head, and walks out the door on the day that person retires.
Each class of work is planned on its own
A shift carries six different classes of work at once: scheduled maintenance, reactive failure response, regulatory inspection under a hard deadline, risk-based proactive visits, liquid management, and routine information collection.
Each has its own time windows, its own cost of deferring it, and its own qualification requirements, and each is tracked where it originates.
The couplings between them are what nobody plans: a hauler dispatched late induces a well shut-in, and an electrician routed first is what lets a workover proceed.
The result shows up too late to change anything
Field activity reaches the numbers at month close, and the discovery that a high-value well sat compromised while crews worked nuisance items arrives billing cycles later.
Every close-out held the answer to whether that exception was worth the visit, and in a classical deployment that answer goes nowhere, so the queue in year five is no smarter than the queue in year one.

The intervention
One loop, running every night and every shift.
WellOPS is the Pump by Priority platform for production operations.
It reads the systems of record the operator already owns, prices what it finds, ranks it against everything else open, sequences it into a day a crew can actually drive, and learns from how the day closed.
- Value density first, then drive time, access, crew qualification, and hours available.
The ranked list, sequenced into a drivable day
Crew A’s day
7 stops · 2h 39m driving · $10,331/d
Drive is modeled inside a synthetic field, not measured on real roads. Synthetic demo data, generated.
- SCADA, production accounting, historian, CMMS, and the well master reconciled into one record, then every exception priced in dollars per day at risk.Today’s plan · 06:005 Critical2 High#Well, reason, deferred, driveWellValue / day01Alderridge F-7HHigh Fluid Level, CriticalHigh Fluid Level · 96 BOE · 8 mi$3,939/d02Pellmarsh 1-5ESP Underload, CriticalESP Underload · 71 BOE · 17 mi$3,336/d03Sabelgate Unit 7Compressor Down, CriticalCompressor Down · 63 BOE · 15 mi$2,807/d04Bringate 1-4Gas Lock, CriticalGas Lock · 53 BOE · 9 mi$2,711/d05Thanegate Unit 1High Fluid Level, CriticalHigh Fluid Level · 47 BOE · 14 mi$2,262/d06Thanegate G-5Plunger Not Cycling, HighPlunger Not Cycling · 77 BOE · 12 mi$1,635/d07Harlfield Unit 1HPlunger Not Cycling, HighPlunger Not Cycling · 87 BOE · 10 mi$1,502/dTop 7 of 46 flags shown · synthetic demo dataPlan total, 4 crews · 25 stops $34,214/d · 375 mi
The ranked plan the crew sees by 6 AM: the morning's work, each item carrying its dollars per day at risk and the reason it ranked where it did. 148 wells, one morning. Synthetic demo data, generated.
- Every job competes on the same score: production at risk, probability of a successful intervention, equipment condition, safety and regulatory constraint, crew capability, drive time.
What goes in, and what the engine does with it
DataHub reads SCADA, the historian, production accounting, the CMMS, and the well master, and reconciles them into one record per well.
The prioritization engine scores every open exception and every open job on that record: production at risk in dollars per day, probability that an intervention recovers it, equipment condition, safety and regulatory constraints, crew capability, and drive time.
Severity color and time in a queue describe an exception. Dollars order the day.
Route Optimization then turns the ranked list into a day. Value density leads, and the solver works inside the real constraints: hours available, qualification to do the job, access and road conditions, and the jobs that have to happen regardless of what they earn.
Work priced below the economics of a visit is logged and watched rather than driven to.
- The ranked plan, the work order, and the capture screen are the same screen. The close-out is the record.
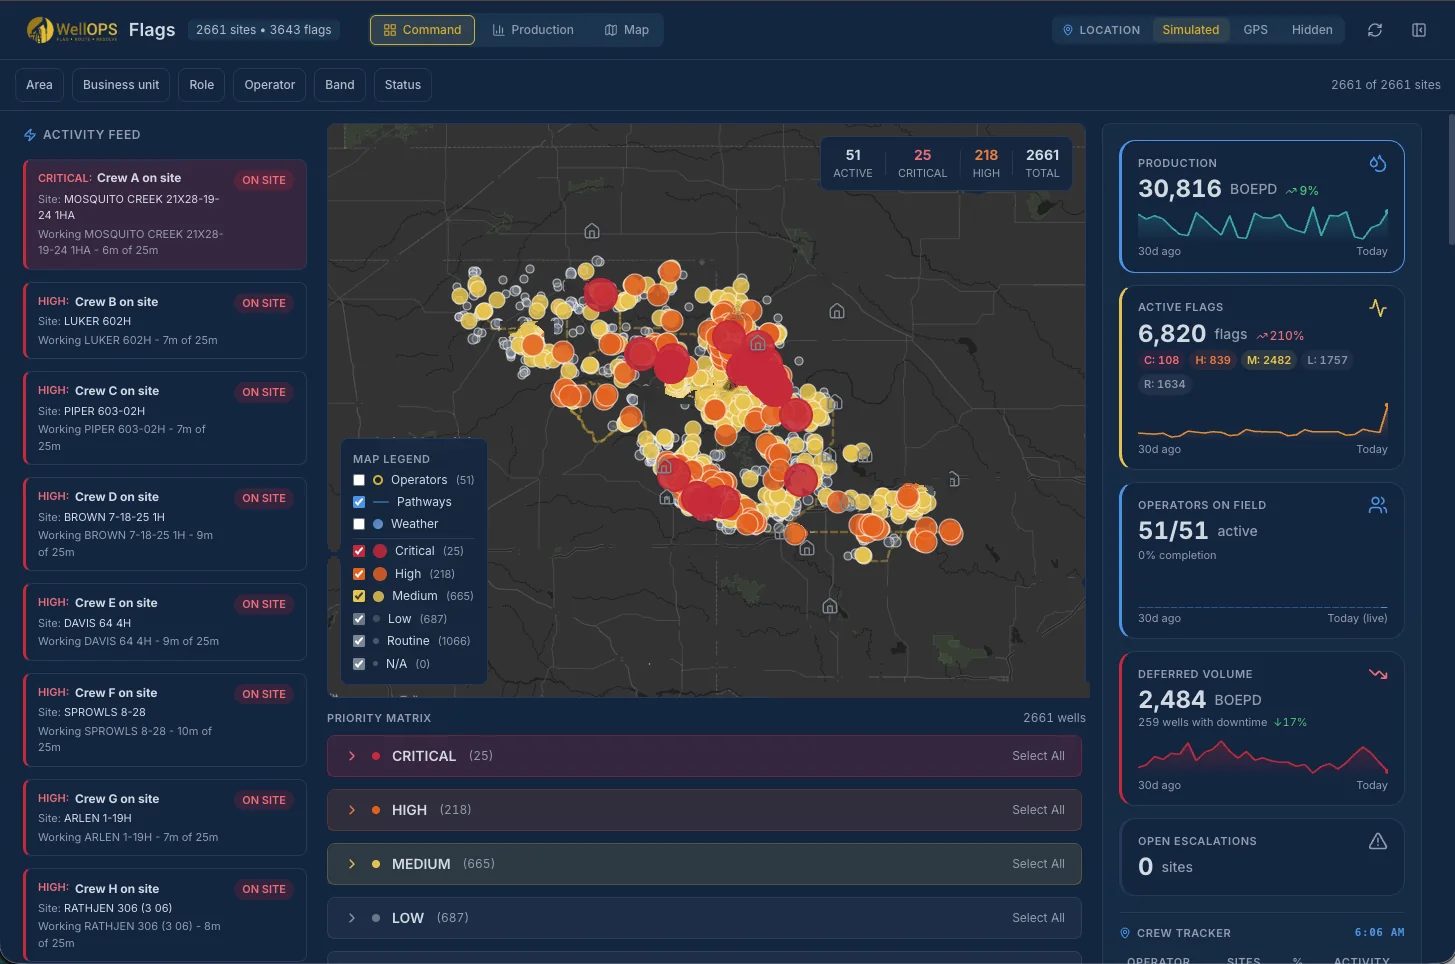
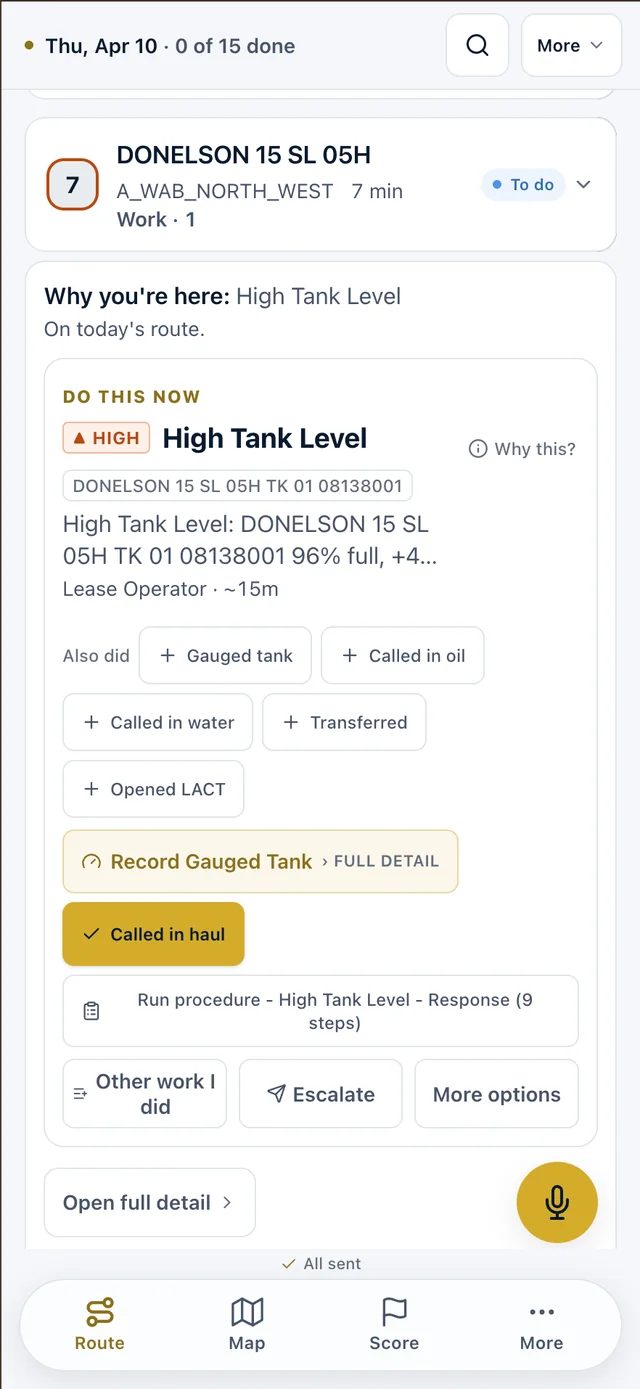
The same loop at both ends: the Command view at the desk, the ranked task in the truck · Demo screen, synthetic data - The accrual is booked with the work, and every completed job feeds the ranking that produces tomorrow.
What closes the loop
The crew works the plan on the same surface the plan arrives on, and closes it out there: what was found, what was done, the readings taken, the volumes captured. That close-out does two jobs at once.
It books the accrual with the work instead of at month close, and it returns to the engine as evidence, so the next ranking knows which interventions actually recovered production on which equipment in which conditions.
That is the part that compounds. A ranking that learns from its own close-outs gets better every week it runs, and the judgment it accumulates belongs to the operation rather than to any one person in it.
The ranked list, sequenced into a drivable day
Crew A’s day
7 stops · 2h 39m driving · $10,331/d
Drive is modeled inside a synthetic field, not measured on real roads. Synthetic demo data, generated.
- FlagSignals from the systems of record become one reconciled exception per well.
- PriceEvery exception carries dollars per day at risk, not a severity color.
- RankPriced work competes against all other open work on one economic ruler.
- RouteThe ranked list becomes a drivable day inside the real constraints.
- ExecuteThe crew works the plan and closes it out where the plan lives.
- LearnClose-outs return to the ranking, and the accrual is booked with the work.
The scoring, routing, and learning mechanisms above are documented in full in the four WorkSync white papers, now published in their entirety: Pump by Priority, Optimal Route Planning, Taking Pump by Exception to the Next Level, and Automated Hydraulic Model Builds.
After
Measured in the field. Not modeled in a spreadsheet.
- 15%Free cash flow uplift, same crewDeployment figure, measured across 5,000+ wells in live deployments
- 35%Fewer field miles, same production coverageDeployment figure, same production coverage
- 5,000+Wells under coverage, three basinsDeployment fact, counted from the deployed asset hierarchy
- 40%Lower liquid-hauling inventoryDeployment figure, against the pre-deployment hauling baseline
- 60%Less redundant tank gaugingDeployment figure, same tank-battery population
- 0Tank-induced shut-insDeployment figure, across the measured period on covered tank batteries
Standard rollout on the productized platform: crews live in 4 weeks
Recovering deferred production is worth a 2 to 5% production uplift. That figure is modeled, aligned to the published Alvarez and Marsal worked example rather than quoted from it, and it sits outside the measured tiles above for exactly that reason.
The mechanism behind it is the ranking itself: deferral priced in dollars at risk, and recovery work dispatched biggest dollars first.
About the customer: a top 25 private producer running 5,000+ wells across the Western Anadarko, Permian, and Wyoming. WorkSync publishes the scale, the basins, and the measured figures, and keeps the name confidential at the customer’s request.
Every number on this page appears with its measurement basis on the numbers page. Results are not projections, and what transfers to your operation is exactly what the pilot measures.
Deployment one took 12 weeks; the productized platform now stands up in 4.
That first rollout carried custom integration work for each basin, with basin one live at week 4 and all three basins on the same loop by week 12. Everything learned in those 12 weeks is now product.
A second deployment
The same pattern, applied to engineering work.
A midstream pipeline operator maintains hydraulic models of a 2,000+ mile network. The before state is the same shape as the one above: the information exists, and turning it into a decision costs weeks of a skilled person’s attention.
FlowSync builds the model from the PDFs, GIS, and SCADA the operator already has, and the engineer verifies and signs instead of transcribing.
A build that consumed weeks of document archaeology and manual entry compresses to minutes of verification.
Gathering and transmission mileage reconciled into the model inventory, with models, data, and studies flowing through one platform.
Common questions
Questions about these outcomes
Who is the customer behind these outcomes?
A top 25 private producer running 5,000+ wells across the Western Anadarko, Permian, and Wyoming. WorkSync publishes the scale, the basins, and the measured figures, and keeps the name confidential.
The anonymity is deliberate and it is the customer’s call, not a hedge on the numbers.
Are these outcomes measured or modeled?
Measured.
The free cash flow uplift, the field miles, the hauling and gauging figures, and the tank-induced shut-in count are all deployment figures: they come from the operator’s own accounting close, route logs, and downtime records, compared against a pre-deployment baseline on the same asset base.
Exactly one figure on this page is modeled, the 2 to 5% production uplift from recovered deferred production, and it is labeled modeled everywhere it appears and kept apart from the measured set. Every figure WorkSync publishes carries its measurement basis on the numbers page.
Did the field organization grow to produce these results?
No. Same crew is the control on the free cash flow figure: no incremental headcount in the comparison window, the same wells, and the same trucks. The uplift comes from where the crew day was spent, not from more crew days.
How long did the deployment take?
Deployment one took 12 weeks; the productized platform now stands up in 4. That first rollout carried custom integration work per basin, with basin one live at week 4 and all three basins on the same loop by week 12.
On today’s platform the cadence is fixed: week 1 connect the data, week 2 configure and rank, week 3 put the plan in the field, week 4 measure the result.
Did the operator replace SCADA, CMMS, or production accounting to get this?
No. The systems of record stayed exactly where they were. WellOPS reads from them, prices and ranks the work, routes the crew, and writes the outcomes back to the systems the operator chooses. Read-only in, ranked work out.
Keeping the existing stack is what made a four-week standing start possible in the first place.
What part of this transfers to my operation?
What the pilot measures. Bring one field’s data and WorkSync ranks the work your crew would have run, prices it, and shows the economics against your own baseline.
The figures on this page describe one deployment at one producer; your number is your number, and the Impact Guarantee means license fees start when it moves.
Go deeper
The record, the numbers, and the method behind them.
What would your field work on tomorrow?
Bring one field’s data. We rank the work, we show you the economics, and you decide whether it is worth doing. License fees start when your number moves.